VoxFocus

THE ACOUSTIC AI LAYER

We separate the voice from the noise.

AI-powered speech separation for industrial environments — in real time.

COMMANDHuman ↔ Human SENSEHuman → Machine ONE CORELocal Acoustic AI

Hear how well our AI Audio Core isolates voices.

Press play, then switch between Noise and VoxFocus while it plays. Best with headphones.

Construction drill0:00 / 0:25
Factory floor0:00 / 0:25
Aircraft engine0:00 / 0:25
SPEECH-TO-TEXT TEST · OPENAI WHISPER, UNCHANGED
1650%word error rate on the raw microphone
5%the same clip with VoxFocus SENSE
See the test →
SENSE · Industrial application concept

THE PROBLEM STARTS AT THE MICROPHONE

Clear communication.
Even when it gets loud.

Machines, tools and changing noise mask speech. People have to repeat instructions. Voice systems receive a signal that is difficult to understand.

VoxFocus develops the acoustic layer between the real world and the receiver. Our AI Audio Core separates relevant speech from background noise before it reaches the ear or digital speech processing.

THE PRODUCT FAMILY

One core. Two industrial paths.

Shared technology.
A clear role for each application.

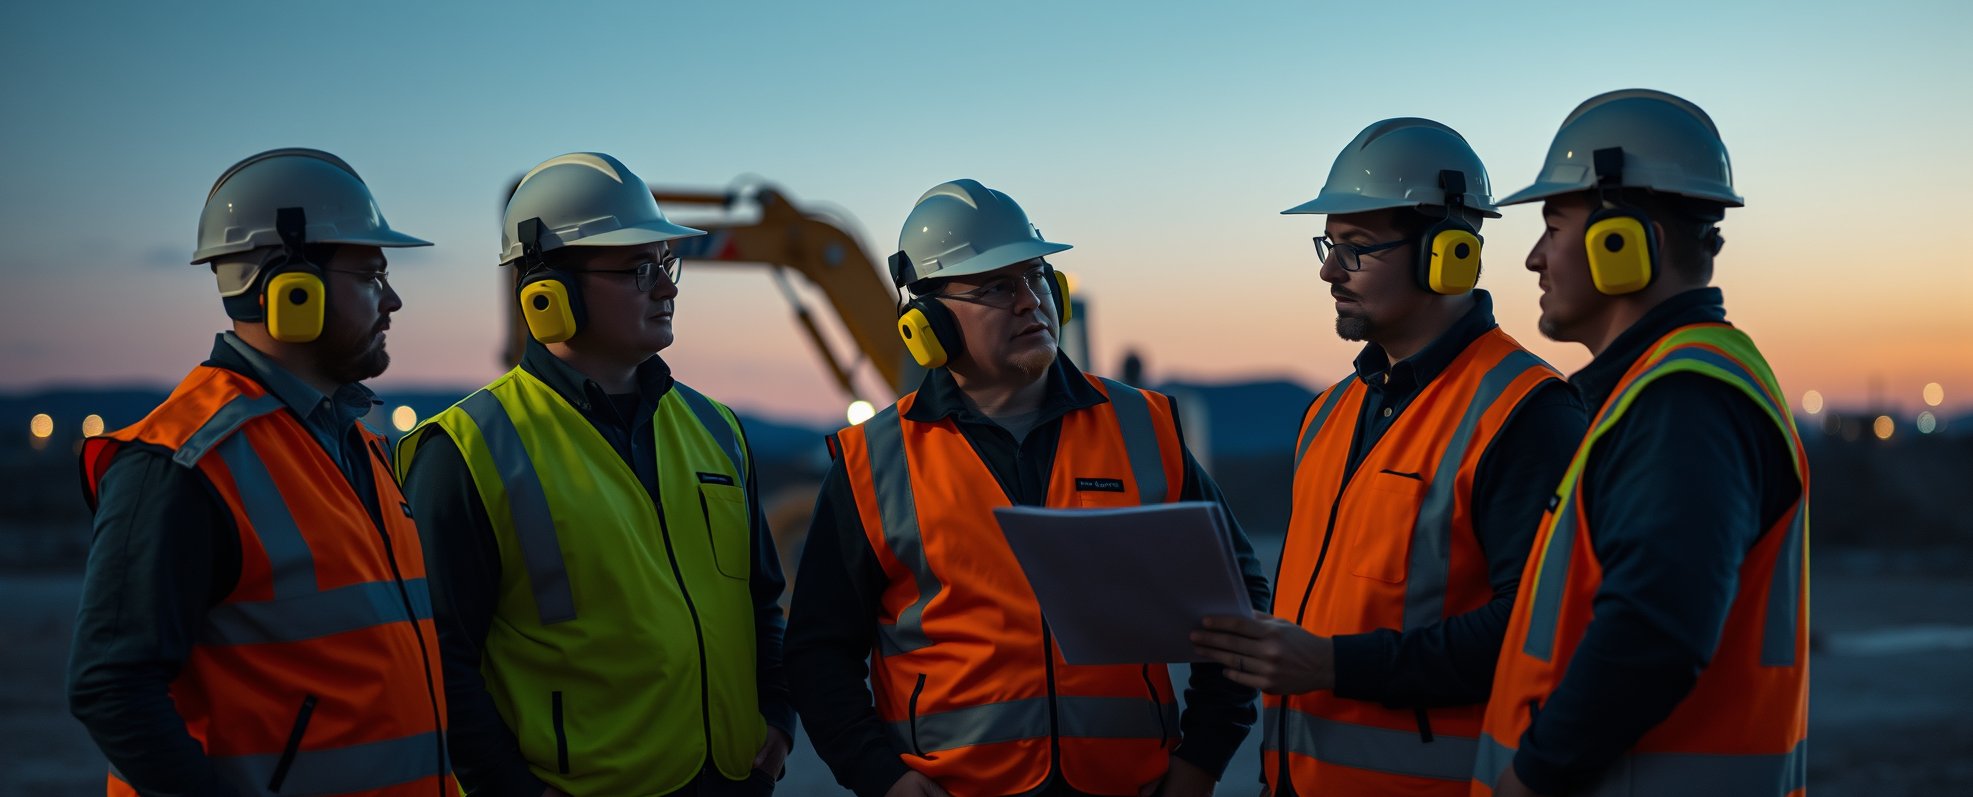
Team briefing on a construction site, everyone wearing hearing protection (symbolic image, AI-generated) WORKING PROTOTYPE

HUMAN ↔ HUMAN

COMMAND

Wear protection. Understand speech.

An intelligent communication layer for earmuff hearing protection: an external hub processes audio locally and delivers the separated speech to the wearer.

  • For manufacturing, maintenance and noisy workplaces
  • A modular concept combining a hub and specified hearing protection
  • Direct industrial pilots leading to validated configurations
Architecture & product status

Microphones capture the input signal. The hub provides computing power, power supply and signal processing; a compact add-on delivers the speech to the wearer.

The current architecture is a prototype concept. Compatibility, attenuation, warning-signal awareness and everyday usability are assessed for each combination. Universal retrofit compatibility is not assumed.
Explore how it works Request a COMMAND pilot Why it matters →
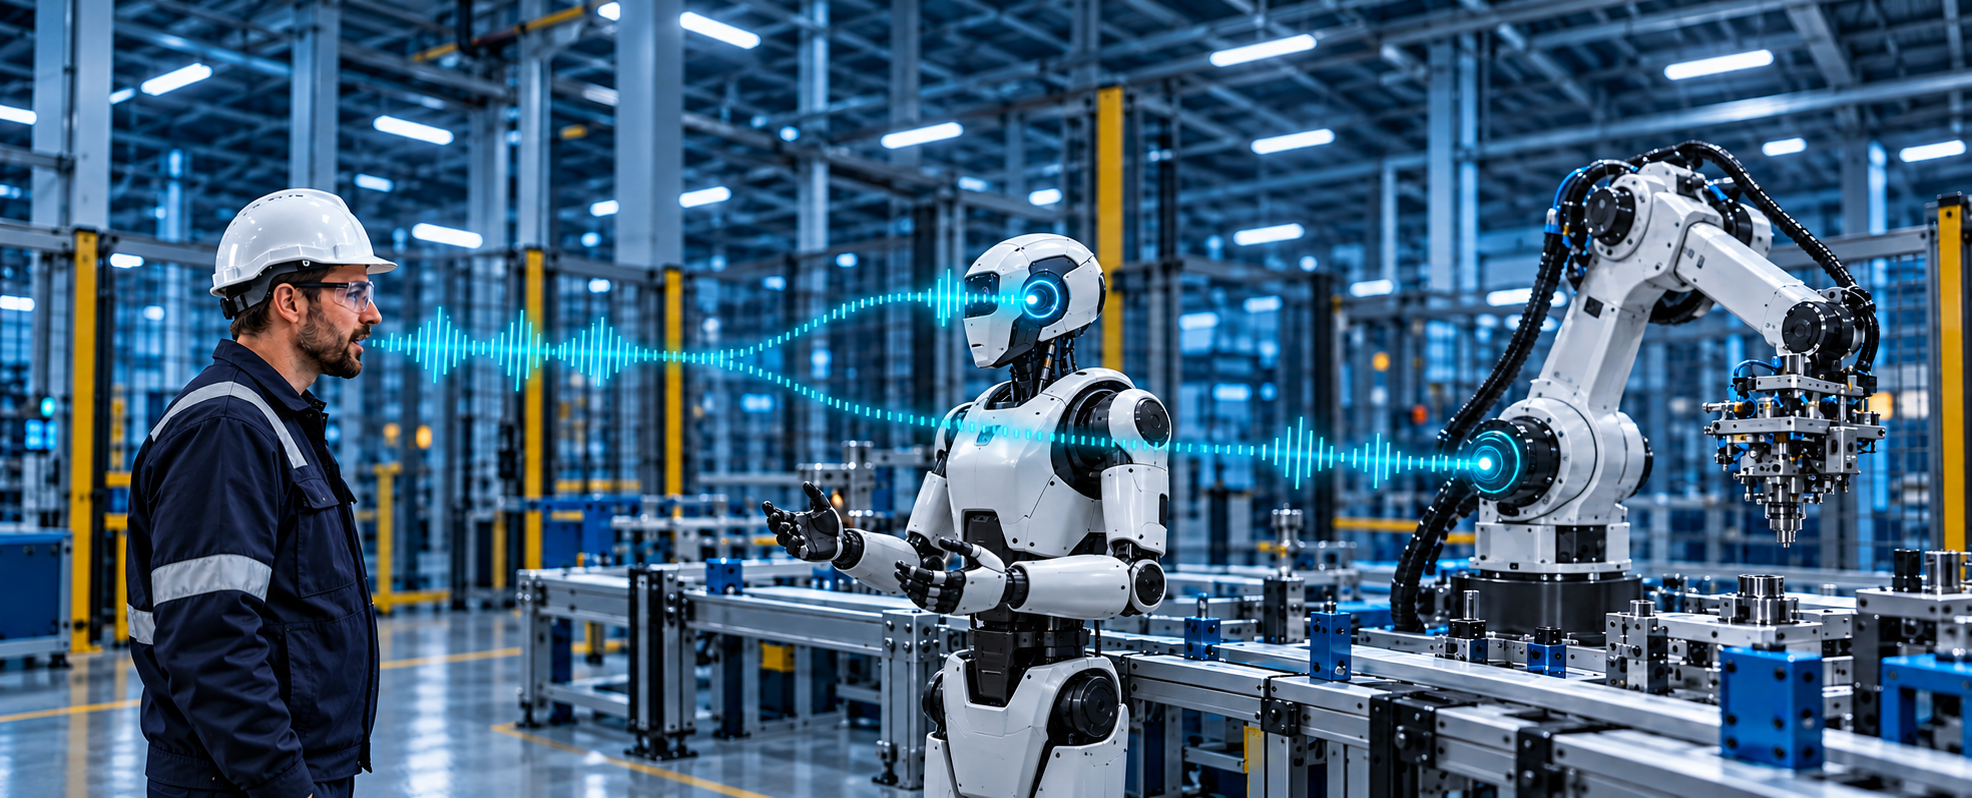
Concept of a worker communicating with a robot and machinery in a factory WORKING PROTOTYPE

HUMAN → MACHINE

SENSE

The acoustic frontend for industrial AI.

SENSE prepares speech for existing speech recognition, HMI systems and robotics. Acoustic separation addresses the point where input quality determines the effectiveness of downstream processing.

  • For machine builders, robotics companies and system integrators
  • Integration before speech recognition and intent processing
  • Module and software integration as planned product paths
Integration & system boundaries

The signal path runs from microphones through the AI Audio Core to existing speech recognition, followed by command interpretation.

SENSE does not replace machine control. Confirmation, authorisation and safety-related control logic remain in the downstream system. Interfaces and functionality are defined with design partners.

Explore how it works Discuss SENSE integration

FUTURE PERSPECTIVE / HUMAN ↔ ENVIRONMENT

AIR

A future application of the technology core to assistive listening and everyday communication. Current development and market entry focus on COMMAND and SENSE.

Future application

Images are symbolic: concept visualisations and AI-generated scenes. They do not depict approved production products.